

People ask “Kubernetes or Docker?” as if these were two brands of the same product, and that framing causes most of the confusion. Docker packages an application into a container. Kubernetes decides where a pile of those containers runs and restarts them when they fall over.
A single Docker host can’t do that second job on its own.
The adoption numbers say a lot about how little the two compete. 82% of container users now run Kubernetes in production, up from 66% in 2023 (CNCF, 2026), which reflects teams pairing the tools far more often than picking one over the other.
What Is Docker

Docker arrived in 2013, released by dotCloud, the company that later renamed itself Docker Inc. The problem it went after was an old one: code that works on one machine and breaks on the next.
A container built with Docker carries its own runtime, libraries and settings. It behaves the same on a laptop, a test server or a production box, and that’s most of the appeal. The image format Docker popularized became the default way to package software before shipping it.
Day to day, you use Docker to build images from a Dockerfile, run and restart containers through the Docker Engine, push images to a registry, and keep each container’s filesystem, network and processes isolated from the others.
None of that needs a cluster or a scheduler. Docker is built for one machine at a time. That single-host focus is what separates it from Kubernetes, and it’s the reason people compare them at all.
If you’re typing Docker commands every day, you’ll end up with a reference sheet open anyway. This Docker cheat sheet covers the commands people reach for most.
What Is Kubernetes
Google built Kubernetes internally, drawing on lessons from an older system called Borg, and handed it to the newly formed Cloud Native Computing Foundation in 2015.
Docker runs one container on one host. Kubernetes coordinates hundreds or thousands of containers spread across a cluster of nodes, and it works with pods rather than single containers (a pod is the smallest unit its scheduler manages).
The adoption figures are hard to ignore. 82% of container users now run Kubernetes in production, up from 66% in 2023 (CNCF, 2026). Namespaces are the preferred isolation method for 88% of Kubernetes users, a sharp jump year over year (CNCF, 2025).
Not long ago, Kubernetes was dismissed as overkill for anyone but large platform teams. That view has mostly faded, at least among organizations already running containers at any real scale.
Kubernetes leans on a microservices architecture style almost by design. Splitting an app into independent services is what makes automated scheduling worth the setup effort.
Once you start writing manifests, keep a reference nearby. This Kubernetes cheat sheet lists the kubectl commands worth memorizing.
What Is the Core Difference Between Kubernetes and Docker
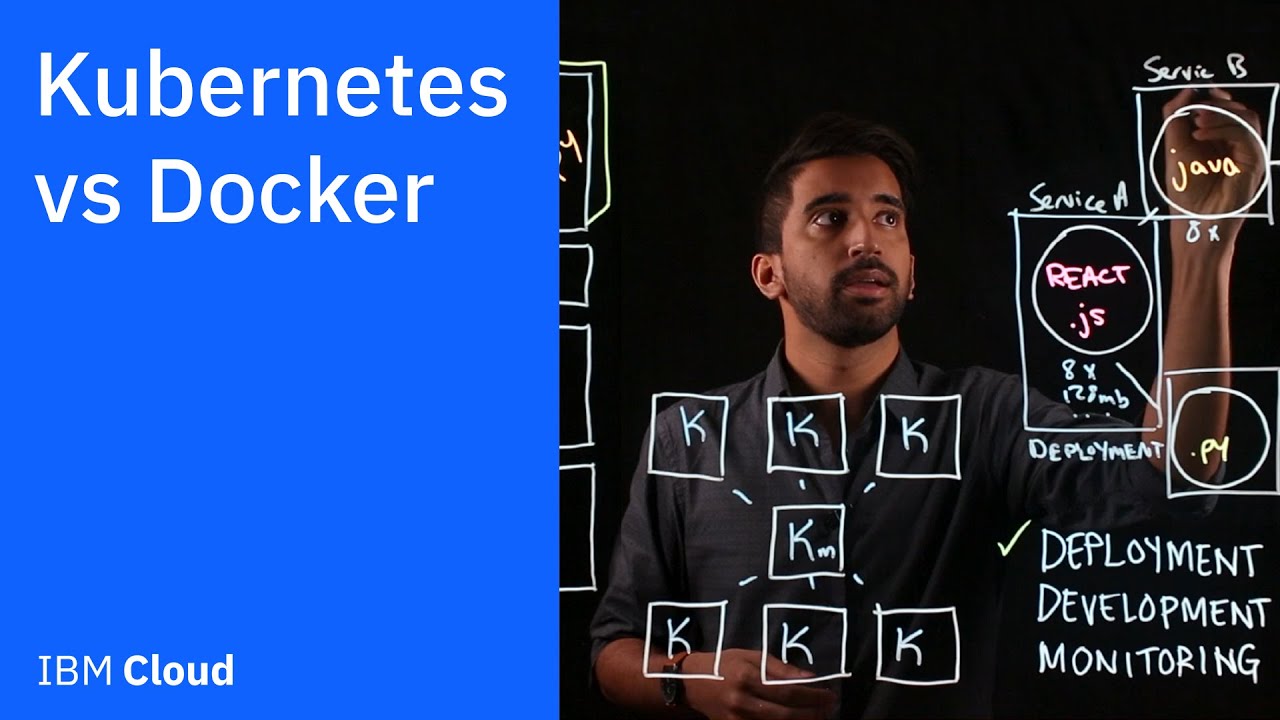
They sit at different layers of the same stack. Docker builds and runs individual containers on a single machine, while Kubernetes manages many containers across many machines at once. Neither one is trying to do the other’s job.
| Aspect | Docker | Kubernetes |
|---|---|---|
| Primary function | Builds and runs individual containers | Orchestrates containers across a cluster |
| Operating scope | Single host | Multi node cluster |
| Scaling approach | Manual, via Compose or scripts | Automated horizontal pod autoscaling |
| Networking model | Bridge network on one host | Cluster networking through CNI plugins |
Docker builds the image and Kubernetes schedules and runs it. A container still shares the host kernel either way, which is where it differs from a full virtual machine that boots its own operating system.
Removing Docker as a runtime also doesn’t remove Docker images from the workflow.
Most teams outgrow Docker alone well before they outgrow the container format itself. That’s usually when Kubernetes enters the picture.
Docker Architecture and Components
A daemon process does the real work of building, running and managing containers. The docker command you type is only a client, and it talks to that daemon over an API.
The main pieces are the daemon (dockerd), which runs continuously in the background, the command line client, images built in layers and cached for speed, and a registry where finished images get stored and pulled from.
Every instruction in a Dockerfile adds a layer to the image, and Docker caches the unchanged ones so rebuilds go faster. That’s why people order instructions carefully, with the parts that change least at the top.
Isolation comes from two Linux kernel features, namespaces and cgroups. Docker didn’t invent either one.
Images get pushed to a container registry, public or private, before anything else can pull and run them.
Underneath the daemon, Docker now hands the actual container execution to containerd, a lower-level runtime it also donated to the CNCF. Worth remembering for later, since containerd is also what most Kubernetes clusters use to run containers.
Kubernetes Architecture and Components

Kubernetes splits into two halves. A control plane makes the decisions and worker nodes carry them out. Lose track of which half does what and the documentation gets confusing fast.
Control Plane Components
Scheduling, state and configuration decisions all happen here. The API server is the entry point for every kubectl command and internal request, and etcd, a key value store, holds the cluster’s entire state. The scheduler decides which node a new pod lands on. The controller manager keeps the actual state matching the desired one.
Nothing in this layer runs application containers directly. Its job is coordination, not execution.
Worker Node Components
Every worker node runs the pieces that actually execute containers and report back to the control plane.
| Component | Role |
|---|---|
| kubelet | Agent that starts and monitors containers on the node |
| Container runtime | Runs the containers themselves (containerd or CRI-O) |
| kube-proxy | Handles network rules and routing on the node |
The kubelet talks to the runtime through the Container Runtime Interface, a standard that lets Kubernetes swap runtimes without rewriting itself.
It’s also why Kubernetes no longer needs Docker directly to run Docker-built images.
How Kubernetes and Docker Work Together

Docker builds the image, and Kubernetes takes that same image and runs it across a cluster. Nothing about the format changes between the two, so a container built with Docker runs correctly under Kubernetes.
The usual path starts with a Dockerfile that describes the application and its dependencies. You build the image locally, push it to a registry, and reference it in a Kubernetes deployment configuration. Kubernetes then pulls the image and schedules it onto whichever nodes have room.
Kubernetes itself stopped talking to Docker directly a while back. Dockershim, the component that let the kubelet call Docker Engine, was deprecated in Kubernetes v1.20 and removed outright in v1.24 (Kubernetes, 2022).
That removal changed how Kubernetes runs containers, not what containers it can run. Docker-built images kept working unchanged, because Kubernetes shifted to containerd and CRI-O through the Container Runtime Interface instead.
Teams relying on Docker Engine specifically inside a cluster can still bridge the gap with cri-dockerd, an adapter maintained by Mirantis and Docker for exactly that case.
Most continuous integration setups automate this build-to-deploy flow end to end. A well-built build pipeline handles the image build and push automatically, so the only manual step left is approving what gets deployed.
Scaling: Docker vs Kubernetes
Docker scales when you run more containers, either by hand or through Docker Compose on a single host. Kubernetes watches load and adds or removes pods on its own, across as many nodes as the cluster has.
On the Docker side, a person or a script sets the container counts. Compose files define fixed replica counts, and nothing reacts to real-time load changes.
Kubernetes has horizontal pod autoscaling that reacts to CPU, memory or custom metrics. Failed pods get restarted without anyone touching them, and rolling updates replace pods gradually so there’s no downtime.
Spotify’s migration from its homegrown orchestrator to Kubernetes shows what that gap looks like in practice. In the company’s 2019 case study, its largest Kubernetes-run service handled about 10 million requests per second, and average CPU utilization improved two to threefold after the move (Kubernetes, CNCF case study).
Gains like that come from bin packing and autoscaling. Manual container scaling on Docker alone can’t replicate them.
What it really comes down to is who makes the horizontal vs vertical scaling call, a person or a controller.
Teams chasing uptime guarantees usually care less about raw scale than about high availability, and that’s where Kubernetes’ self-healing behavior earns its keep.
Networking: Docker vs Kubernetes
Docker networking works on a single host. A bridge network lets containers talk to each other and to the outside world.
Kubernetes networking spans an entire cluster, and that needs a different set of rules.
| Aspect | Docker | Kubernetes |
|---|---|---|
| Default model | Bridge network on one host | Flat network across all nodes |
| Cross-host communication | Requires manual setup (overlay networks) | Built in, handled by a CNI plugin |
| Service discovery | Container name resolution on one host | Cluster-wide DNS for every service |
A few extra pieces sit on top of that. An ingress controller routes outside traffic to the right service inside the cluster, and kube-proxy handles the low-level routing rules on each node. A service mesh like Istio adds encryption and traffic control between services.
That last one isn’t automatic. Adding a mesh is a deliberate decision, and increasingly not the default one.
Service mesh adoption actually dropped from 50% in 2023 to 42% in 2024, largely over operational overhead concerns (CNCF, 2025).
Most of that overhead comes from the sidecars, certificates and control planes a mesh needs on top of Kubernetes networking that already works. Envoy, the proxy that Istio and several other meshes build on, was originally built at Lyft and later donated to the Cloud Native Computing Foundation.
Traffic entering the cluster typically passes through a reverse proxy before an ingress rule decides where it goes next.
Inside the cluster, a Kubernetes Service usually works as a load balancer, spreading requests across every healthy pod behind it.
Kubernetes vs Docker Swarm
Swarm is the orchestrator Docker built directly into its own Engine. Kubernetes is a separate and far larger project, with more moving parts and a much bigger ecosystem behind it.
| Factor | Docker Swarm | Kubernetes |
|---|---|---|
| Setup | One command, docker swarm init | Multiple components to configure |
| Learning curve | Shallow, close to plain Docker | Steep, its own vocabulary and tooling |
| Ecosystem | Small, mostly Mirantis-driven | Large, CNCF-wide |
Swarm is quick to set up and feels familiar if you already know Docker Compose. The downsides are limited autoscaling and a much smaller tool ecosystem.
Kubernetes handles complex, multi-team workloads at real scale, and every major cloud provider and the CNCF stand behind it. You pay for that with a steeper learning curve and heavier operational overhead.
Swarm isn’t dead, whatever the market share numbers suggest at a glance.
Mirantis reports more than 100 customers running Swarm in production, spanning over 10,000 nodes across roughly 1,000 clusters and orchestrating more than 100,000 containers (Mirantis, 2024).
MetLife, Royal Bank of Canada and S&P Global are among the enterprises Mirantis names as running Swarm workloads.
When to Use Docker Alone vs When to Use Kubernetes

Docker alone fits one app on one host, run by a small team that doesn’t want cluster management on its plate. Kubernetes fits the opposite case, where scale and uptime requirements outgrow what one machine can reasonably handle.
When Docker Alone Is Enough
Local development environments work fine on Docker alone. So do small internal tools with predictable, low traffic, side projects and MVPs with no dedicated ops function, and single-server applications that don’t need to survive a node failure.
Plenty of production apps run this way for years without issue. Teams without a full DevOps function often keep it that way on purpose.
When Kubernetes Is Worth the Overhead
The overhead starts paying for itself once uptime and growth become real business requirements instead of nice-to-haves.
Multiple teams deploying independently into the same environment is one sign. Traffic that spikes unpredictably and has to scale in minutes rather than hours is another, along with any requirement to survive a node or zone failure without downtime.
At that point Kubernetes earns its complexity, because software scalability stops being theoretical and becomes a promise to users.
When Kubernetes Does Not Make Sense
Kubernetes solves real problems, but at a cost that not every team should pay. Small teams without dedicated operations capacity often end up managing a cluster instead of building their product.
It tends to fail for small teams with no one assigned to cluster maintenance, for single-server applications with stable and predictable load, and for short-lived projects where setup time outweighs any operational benefit. Budgets that can’t absorb the cost of running mostly idle infrastructure are a problem too.
That last point isn’t a guess. Average CPU utilization across Kubernetes clusters sits at just 8%, down from 10% the year before (CAST AI, 2026).
Most of that capacity is provisioned out of caution and never used by anything running in production.
signals moved Basecamp, HEY and other applications off cloud Kubernetes and onto its own hardware in 2023. The team had first tried Google Kubernetes Engine and retreated after network control plane outages, then ran legacy apps on Amazon EKS, and finally dropped a plan to run Kubernetes on its own hardware as too expensive and operationally complicated (37signals, 2023).
They replaced it with plain Docker containers deployed by Kamal, a tool the team built, with no control plane to run. For a mature, stable workload with a dedicated operations team, that setup covers the same ground at a fraction of the operational cost.
Installing and Setting Up Docker and Kubernetes
Docker takes minutes to get running. A real Kubernetes cluster takes a bit more planning.
- Install Docker Engine or Docker Desktop on the local machine
- Confirm the daemon is running and build a test image
- Install a local Kubernetes tool, like Minikube or Kind
- Point kubectl at that local cluster and deploy a test workload
- Move to a managed service (EKS, GKE or AKS) once local testing works
The how to install Docker guide covers platform-specific steps, since Windows, macOS and Linux each handle it slightly differently.
On the managed side, EKS integrates tightly with the rest of AWS, and GKE is run by Google, the company that created Kubernetes. AKS is the default choice for teams already on Microsoft’s cloud.
None of them remove the learning curve entirely. They only take the control plane off your hands.
Migrating From Docker to Kubernetes
Most migrations start from the same place, a working Docker Compose setup that a team has outgrown. Converting it into Kubernetes manifests isn’t a one-to-one translation, even though the containers underneath stay the same.
Environment variables and secrets tend to break first, since they need a different storage mechanism. Networking assumptions baked into the old Compose file come next, followed by volume mounts, which behave differently under persistent volume claims.
Teams usually start by exporting the existing Compose file (the what is Docker compose explainer covers how it’s structured), then convert services one at a time rather than all at once.
Helm charts replace raw manifests fairly quickly once a team has more than a handful of services to manage.
Testing the conversion against a local cluster with Kind catches most networking and volume mistakes before they reach production.
Treat the resulting manifests as infrastructure as code from day one. It saves a second migration later, when someone inevitably asks for version history on the cluster config.
Tools That Support the Docker and Kubernetes Ecosystem

Neither platform works alone in practice. A working setup usually leans on a handful of surrounding tools.
| Tool | Purpose | Typical use |
|---|---|---|
| Helm | Package manager for Kubernetes | Templating and versioning deployments |
| Rancher | Cluster management platform | Running and monitoring multiple clusters |
| Prometheus | Metrics and monitoring | Tracking cluster and application health |
| Docker Hub | Public image registry | Storing and pulling container images |
Helm is the one that sticks around. It packages a full application rather than a single container, handles versioning and rollbacks through charts, and graduated to CNCF status in 2020, a sign of broad and sustained adoption.
Helm sees more than 2 million downloads a month and its repository has crossed 30,000 GitHub stars (CNCF, Helm Project Journey Report).
AT&T, Conde Nast, Microsoft and VMware are among the organizations CNCF named as running Helm in production when the project graduated.
That kind of standardization usually improves collaboration between dev and ops teams, since both sides end up reading the same chart instead of different scripts.
Private registries, built on the same format as Docker Hub, tend to replace it once security or compliance requirements enter the picture.
FAQ on Kubernetes Vs Docker
Is Kubernetes a replacement for Docker
No. Kubernetes stopped using Docker Engine as its runtime when dockershim was removed in v1.24, but that didn’t make it a replacement for Docker as a build tool.
Docker still creates the container image, and Kubernetes schedules and runs that image across a cluster through containerd or CRI-O. Most production stacks use both together.
What does it cost to run each in production
Docker costs whatever the single host costs, since it runs no control plane of its own.
Kubernetes adds cluster overhead. Managed services like EKS or GKE bill for the control plane plus every worker node, and average CPU utilization across clusters sits at just 8% (CAST AI, 2026).
What are common mistakes when adopting Kubernetes too early
Teams adopt Kubernetes before they have enough services to justify it, then spend more time managing YAML than shipping features.
Skipping resource limits and running a single-node cluster in production are the most common early mistakes, and each one erases the platform’s main benefit.
What Should You Do First After Weighing Kubernetes Vs Docker?
Kubernetes vs Docker turns out to be a sequencing question more than a permanent choice. Teams containerize with Docker first, run that container in production as-is, and bring in Kubernetes only once traffic, team size or uptime requirements exceed what a single host can handle.
In order, that means containerizing the application with Docker, running it on a single host or Swarm, and moving to Kubernetes when traffic or team size demands it.
82% of container users now run Kubernetes in production, while average cluster CPU utilization sits at just 8%, a gap that suggests many of those clusters are heavily over-provisioned.
The operational cost only pays off once a workload already runs somewhere, which is why app deployment becomes the next practical decision.

- How to Turn On Dark Mode in Notepad++ (Built-In, No Plugin) - October 3, 2026
- PostgreSQL Cheat Sheet - October 2, 2026
- How to Repair a Corrupt SQL Server Database Without Any Data Loss - October 2, 2026


