

Git is a distributed version control system. Every clone carries the full project history, so commits and history lookups run without a server. There’s a second meaning, and it’s less flattering. In British slang, a git is an unpleasant person.
Linus Torvalds picked that word in April 2005 for the tool he wrote to manage Linux kernel development after BitKeeper’s free license ended.
The README in Git’s initial commit (2005) gives several readings of the name and offers global information tracker only as the good-mood option, so Git has no official expansion.
What does Git mean?
Two things, depending on who’s talking. In software, it’s the distributed version control system above. In British slang it’s an insult, and Torvalds borrowed the slang word when he named the software in April 2005.
| Sense | Where it appears | Meaning |
|---|---|---|
| Slang noun | British and Irish English | A stupid or unpleasant person, usually a man |
| Software | Programming | A free tool that tracks changes to files across a project’s history |
| Pronoun | Old English | An obsolete word, absent from modern English |
The Cambridge Dictionary marks the slang sense as UK informal. The Online Etymology Dictionary dates it to 1946 and traces it to Scots get, a word for a brat or an illegitimate child.
Git sits in the family of version control tools. It records every change to a project’s files, which means any earlier state can be restored later.
Among developers, nobody means the insult.
The Git project’s About page cites the 2022 Stack Overflow Developer Survey, where 96% of professional developers reported using Git (96.65% in the survey itself).
Where does the name Git come from?

It’s British slang, and the project never settled on an official expansion. The README lists a few readings and leaves the pick to your mood.
What the original README says
The README arrived with the first commit on 7 April 2005. That commit’s message called Git the information manager from hell. The opening lines say the word can mean anything, depending on your mood.
The sound came first. Torvalds wanted a random, pronounceable combination of letters that no common UNIX command already used. Then there’s the insult reading, where the README points you to the slang dictionary and offers stupid, contemptible, despicable and simple as candidates.
On a good day the name stands for global information tracker, for when the tool works. On a bad day, the README supplies an expletive-heavy description for when it breaks.
The README also notes that git mispronounces get, which may or may not be relevant. Etymonline traces the slang word to Scots get as well, a link the README leaves open.
Torvalds’ own explanation
Torvalds gave the name a self-deprecating reason.
Press coverage of the release quoted his joke that he names every project after himself, Linux first and git second. The same tone survives in the Git trademark policy, which lists the slogan the stupid content tracker among the protected marks.
Is “global information tracker” official?
No. The README puts global information tracker next to three other readings, and neither the README nor the trademark policy defines Git as an acronym.
Anyone who says Git stands for global information tracker is repeating one joke option from 2005.
Who created Git, and when?

Linus Torvalds created Git in April 2005, right after the Linux kernel community lost free access to BitKeeper. Junio Hamano has maintained it since July 2005.
- Torvalds made the first commit on 7 April 2005 (Git source repository).
- BitKeeper had been the kernel’s tool since 2002 (Pro Git).
- Git ships under the GNU General Public License version 2.0 (git-scm.com).
- The Software Freedom Conservancy holds the trademark, U.S. registration 4680534 (Git trademark policy).
Why Git replaced BitKeeper
From 1991 to 2002 the kernel passed changes around as patches and archived files. Then it adopted BitKeeper, a proprietary tool for source control management.
In 2005 the relationship between the kernel community and BitKeeper’s company broke down, and the tool’s free-of-charge status was revoked (Pro Git). Torvalds and the kernel developers wrote a replacement around a short list of goals.
- Speed
- A simple design
- Strong support for non-linear development, with thousands of parallel branches
- Fully distributed
- Efficiency on projects as big as the Linux kernel
Who maintains Git today
Torvalds handed maintenance to Junio Hamano in July 2005, a few months after the first commit. Hamano shipped Git 1.0 in December 2005 and has announced releases ever since.
Git’s license and trademark
The license is GNU General Public License version 2.0, an open source license the project chose to guarantee the freedom to share and change the software (git-scm.com).
Software Freedom Conservancy holds the Git marks on behalf of the project. Its policy bars the word Git inside new product names such as Gitpedia, and it bars merchandise. GitHub and GitLab are the two named exceptions, because their licensing arrangements predate the policy.
How does Git work?
Git stores a project as a series of snapshots rather than file-by-file changes, and every clone holds the complete history on local disk. Commits, branches and history lookups therefore run without a network connection, and every object is checksummed with SHA-1 before storage.
Distributed, not centralized
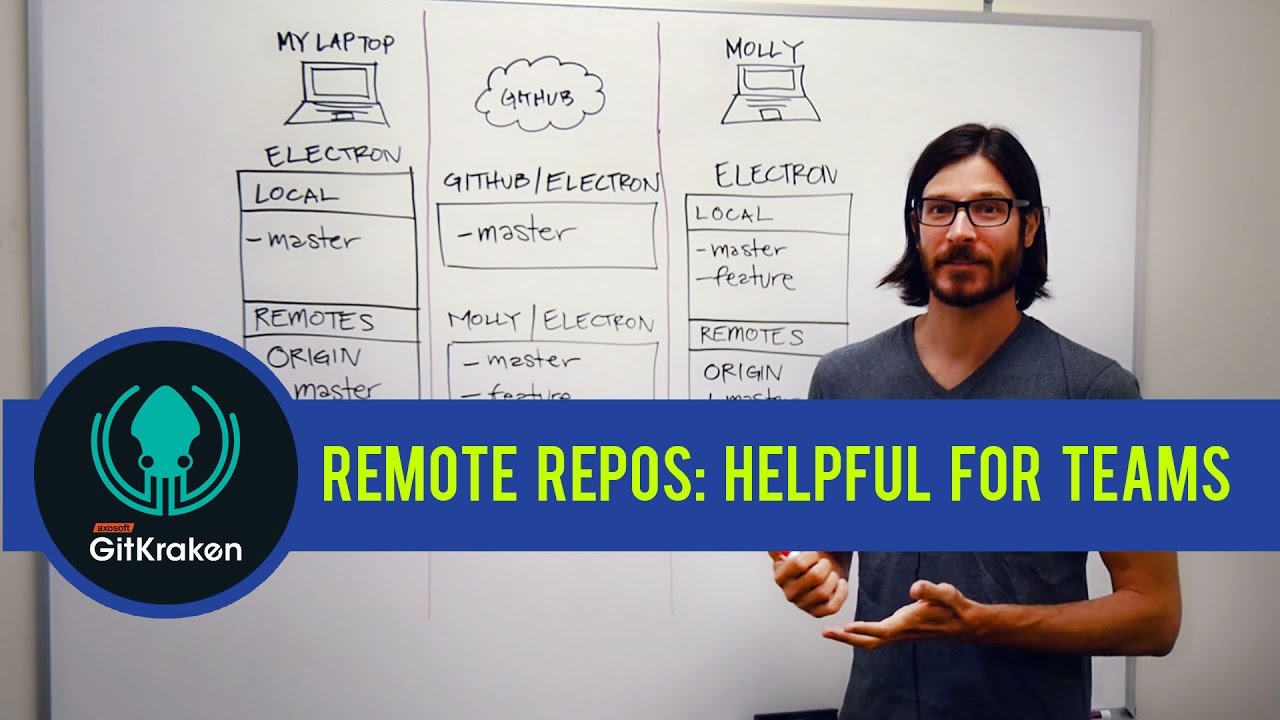
With centralized systems such as CVS and Subversion, the history sits on a server. Pro Git notes that you can edit files offline but cannot commit until you reconnect.
Git keeps the whole history on your disk. You commit locally and push when a connection returns.
Each clone is a complete Git repository, not a thin checkout, so any copy can serve as a backup of the project.
Working tree, staging area and Git directory
The working tree is the checked-out version of the project, the files you actually edit. Next to it sits the staging area, a file that records what goes into the next commit. Git’s technical name for it is the index.
The .git folder holds the metadata and the object database, and cloning copies it.
A file moves through three states: modified, staged, committed.
Snapshots and objects

The Linux kernel’s history runs to 1.4 million commits, and Git stores all of it in 5.5 GB, against 1.7 GB for the current source tree (git-scm.com, figures as of 2025).
That ratio works because a snapshot links to the copy of any unchanged file that Git already stored. The database itself holds blobs, trees, commits and tags, broken down below.
| Object | What it stores |
|---|---|
| Blob | File contents, with no file name or other metadata |
| Tree | A directory listing that points to blobs and subtrees |
| Commit | The top-level tree, parent commits, author, timestamp and message |
| Tag | A reference to another object, often a signed release marker |
Hashes and integrity
Every object gets a 40-character SHA-1 name derived from its content.
Change one byte and the name changes, so corruption can’t pass unnoticed. Git files each object under a directory named for the first 2 characters of the hash, with the remaining 38 as the file name (Pro Git).
A commit hash also covers the commit’s parents, so a single identifier pins down the complete history behind it.
SHA-1 does have a documented weak spot. The SHAttered attack produced a practical collision on 23 February 2017, and Git v2.13.0 moved to a hardened SHA-1 implementation by default.
The project picked SHA-256 as the successor hash in 2018. As of the transition manual last updated in Git 2.55.0 (June 2026), older Git versions cannot read SHA-256 repositories, and the design guide discourages SHA-256 storage on public-facing servers until the protocol supports it. Hosting support is arriving. According to GitLab, it has supported SHA-256 repositories for about a year, and GitHub announced a private beta at Git Merge 2026.
The basic Git workflow

Day-to-day Git work follows one loop. Edit files in the working tree, stage the changes, commit them, then push the commits to a remote repository.
A handful of Git commands carry that loop, and each one maps to a single step.
- Run git init in a project folder to start an empty repository, or git clone with a URL to copy an existing one, history included.
- Edit files in the working tree.
- Run git status to see which files are modified and which are staged.
- Run git add to stage the changes that belong in the next commit.
- Run git commit with a message to store the staged snapshot.
- Run git push to send your local commits to the remote repository.
- Run git pull to fetch other people’s commits and merge them into your branch.
Staging is the step beginners skip past. Git adds changes to the staging area selectively, so one commit can hold part of your edits while the rest waits for the next.
Branching and merging at a glance

A branch in Git is only a reference to one commit, which is why creating one costs almost nothing.
git branch creates, lists and deletes branches. git merge folds the history of another branch into the one you’re on.
Why new repositories start on master
Git’s own default for the first branch is still master.
GitHub and GitLab create main instead, and you can set the name yourself with the init.defaultBranch setting. Git’s BreakingChanges document (last updated in Git 2.55.0, June 2026) says Git 3.0 will switch the default to main and that the project has warned about the change since December 2020. The document still says no release date is planned, but GitLab’s write-up of Git 2.56 (28 September 2026) reports that contributors meeting at Git Merge 2026 sketched a schedule: Git 2.98 in December 2026, then 2.99 and 3.0 together in spring 2027.
What is the difference between Git and GitHub?

Git is version control software that runs on your own machine. GitHub is a hosting platform for Git repositories, and Microsoft agreed to buy it for $7.5 billion in June 2018.
| Name | Type | Owner |
|---|---|---|
| Git | Version control software | The open source Git Project |
| GitHub | Hosting platform | Microsoft |
| GitLab | Hosting platform | GitLab Inc. |
| Bitbucket | Hosting platform | Atlassian |
As a platform, GitHub adds remote hosting, pull requests and code review around a Git repository. A pull request is a ticket that the hosting server manages, not a Git feature.
Nobody needs a host to use Git. It ships with git daemon and gitweb for serving and browsing repositories, and any machine with Git installed and shell access can act as a remote.
Developers still lean on the platform layer, though. In Stack Overflow’s 2025 Developer Survey press release, GitHub led code documentation and collaboration tools at 81%, with GitLab at 36%.
For a fuller breakdown, see this comparison of Git and GitHub.
How does Git differ from Subversion, CVS and Mercurial?

Git is distributed. CVS and Subversion are centralized, and Mercurial is the one rival that shares Git’s distributed design.
| System | Model | Status as of October 2026 |
|---|---|---|
| Git | Distributed | Active, with Git 2.56 released in September 2026 |
| Subversion | Centralized | 1.14.5 stable since December 2024, 1.15.0 in release-candidate testing |
| Mercurial | Distributed | 7.2 released on 29 January 2026, with bugfix release 7.2.4 on 11 August 2026 |
| CVS | Centralized | Last stable release 1.11.23, dated 8 May 2008 |
All four are source control tools that track files through a project’s life. They part ways on how they treat a file’s identity and where the authoritative history sits.
CVS and Subversion
CVS builds on RCS, so history lives in a separate file for each tracked file, and the server accepts changes only against the latest version of a file.
Subversion was founded in 2000 by CollabNet and is now an Apache project. It describes itself as centralized version control with a simple model.
Renames show the gap well. CVS ties history to a file name, so a rename breaks or rewrites that history. Git records no rename at all and infers it when you browse the snapshots.
That inference fails when a file is renamed and edited in the same commit, and Git then reads a deletion plus a new file. Commit the rename first, then the edits.
Mercurial
Mercurial is a free, distributed source control tool, and like Git it gives every clone the whole project history, according to mercurial-scm.org. The same BitKeeper dispute that produced Git spurred it too.
Hosting followed adoption. Atlassian said in 2019 that fewer than 1% of new Bitbucket users chose Mercurial, and Bitbucket, which launched in 2008 as a Mercurial-only service, then removed it.
Removal was first set for 1 June 2020 and extended by 30 days to 1 July 2020. Bitbucket’s blog later recorded all Mercurial repositories as disabled on 26 August 2020.
When a centralized system still makes sense
Stay on Subversion if it works and nothing hurts.
Git can talk to a Subversion server through git-svn, so a team can try Git without moving the repository first. Migration is a project, not a switch.
Where does Git fall short?
Git struggles with large binary files, with repositories that reach millions of files, and with first-time users who meet the staging area without a map.
Large files and repository size
GitHub’s documented limits are blunt. A push containing a file over 50 MiB triggers a warning, and files over 100 MiB are blocked. Repositories should stay under 1 GB, and under 5 GB is strongly recommended.
GitHub Docs send anything past the 100 MiB block to Git LFS, an extension that began in the GitHub community and stores large files as blobs outside the repository itself. The same page says Git is not designed to handle large SQL files or to serve as a backup tool.
Long histories have their own fix. A shallow clone, git clone with the –depth option, skips older commits and saves space and sync time, per Microsoft Learn.
The Windows repository
The Windows codebase held over 3.5 million files and 270 GB when Microsoft’s Azure DevOps team announced GVFS in 2017.
The Git client was never designed for that scale, so Microsoft virtualized the file system and downloaded each file the first time it was opened. A typical developer needs only 50,000 to 100,000 of those files.
Microsoft’s own figures vary a bit. The February 2017 announcement says over 270 GB, while a May 2017 follow-up from Brian Harry put the repository at about 300 GB.
VFS for Git’s own FAQ lists it as Windows-only. In February 2020 the team introduced Scalar to support very large repositories without a virtualized file system.
The learning curve
Git’s command set overlaps in places.
The project’s BreakingChanges document says git restore and git switch cover what git checkout does, yet all three commands stay because checkout is still widely used. Pro Git itself tells newcomers to clear their heads of other systems’ concepts, since Git stores information differently.
A short git cheat sheet covers the daily commands until they stick.
Weighing the trade-offs
On the plus side, GitHub, GitLab and Bitbucket all host Git repositories, branches cost almost nothing, and git-svn offers a path off Subversion.
The downsides are hard file-size ceilings on hosts, extra tooling once a repository passes a few gigabytes, and overlapping commands that confuse newcomers.
For source code in a repository under 1 GB, none of these limits bite in practice. For large binary assets, plan for Git LFS before the first commit.
Git FAQ
How do you pronounce Git?
Git takes a hard g, like the first sound in get, and rhymes with hit. The README in the first commit calls the name a mispronunciation of get, which matches that sound.
Can Git track files other than source code?
Yes. Git stores file contents as blobs, so it versions text, images and data files alike.
It works best on text, and large binary files run into the size limits that hosts such as GitHub enforce.
What is a merge conflict in Git?
Git stops a merge when two branches changed the same lines and it can’t combine them automatically.
It marks the affected files and waits for you to edit them by hand, then you commit the result.
Is a fork the same as a clone?
No. A clone is a Git operation that copies a repository to your machine, history included.
A fork is a hosting-platform feature that copies a repository into your own account on the server, and Git has no fork command.
Do you need the command line to use Git?
No. Git ships with a Tcl/Tk interface called git-gui, and many third-party GUI clients and editor integrations exist.
The core project is a command-line tool, so a GUI is a convenience layer on top of it.
Branching and Merge Conflicts After the Basics
Once the add, commit, push and pull loop becomes routine, branching and conflict handling are the next skills worth learning. Conflicts appear only when branches merge, so branches come first.
Open a branch for each change and merge into the main line in small steps. When a conflict shows up, resolve it right then.
The order follows cause and effect. The shorter a branch lives, the less overlap Git has to reconcile. You pay for that with more frequent merges, and you get smaller conflicts in return.
A step-by-step guide to resolving merge conflicts in Git covers the hands-on side.
Advice about SHA-1 hashes and the master branch name will change when Git 3.0 ships, because its BreakingChanges document plans SHA-256 and main as defaults for new repositories (verified 1 October 2026). Contributors have pencilled in spring 2027 for that release, but the official document lists no date.

- How to Turn On Dark Mode in Notepad++ (Built-In, No Plugin) - October 3, 2026
- PostgreSQL Cheat Sheet - October 2, 2026
- How to Repair a Corrupt SQL Server Database Without Any Data Loss - October 2, 2026


