

Most companies own far more software than they have connections between it. The average enterprise runs 897 applications, and only 29% of them are integrated, according to MuleSoft’s 2025 Connectivity Benchmark Report.
The report draws on interviews with 1,050 IT leaders, conducted with Vanson Bourne and Deloitte Digital.
API integration is one way to close that gap. It links two or more applications through their published interfaces, so data moves and actions fire between them without manual transfer. An online store uses it to pass orders to accounting software. A sales team uses it to write form submissions into a CRM.
What Is API Integration?

Nobody copies a record or uploads a file by hand. That’s the practical difference. The applications talk through their application programming interfaces, and a change in one system produces the right result in another. An order placed in a store can create an invoice in the accounting system within seconds.
Neither application needs access to the other’s internals, and neither has to be built on the same codebase. Each exposes a defined interface, and the integration is the working link built on top of it.
Records move between the systems in a structured format. An event in one can start a task in another, and chain a few of those steps together and you get a workflow that runs with no person in the middle.
How an API Differs From an API Integration
The API is the interface a system exposes. The integration is the connection someone builds on that interface for one specific job.
Say a supplier publishes a stock-lookup endpoint. That’s an API. When a retailer’s system calls that endpoint every night to refresh its availability counts, you have an integration.
An API can sit unused for years. An integration is the API in use, with authentication, field mapping and error handling built around it, and that’s the part that takes the work.
How Does API Integration Work?
One system sends an HTTP request to an endpoint on another system. That system answers with the data you asked for, or with a status code explaining why it couldn’t. Authentication, field mapping and retries all exist to make that exchange repeatable.
Each request carries an endpoint (the URL of a resource), an HTTP method, headers for credentials and data format, and usually a payload. The method says what you want done.
- GET reads a record without changing it
- POST creates a record or triggers an action
- PUT replaces a record, and PATCH updates only part of it
- DELETE removes one
The response carries a status code, and the integration has to treat each class differently. A 2xx code means success, 4xx means the caller sent something wrong, and 5xx means the server failed.
Stripe’s API reference shows the split well. A 401 means no valid API key was provided, while 500, 502, 503 and 504 point to a problem on Stripe’s side. The first needs a fix on your end. The second is worth a retry.
Where Data Mapping and Middleware Fit
Payloads rarely match between systems. One calls the field customer_email, the other calls it contactEmail, and a date arrives as text where the receiver expects a timestamp.
Data mapping translates the field names and converts the types before the data lands. For two systems with simple records, direct calls cover it.
Past that, a middleware layer or a prebuilt connector handles transformation, queuing and delivery, so each application keeps one connection instead of many.
API Integration Examples: Payments, CRM, Messaging and Stock Sync
Payments, CRM updates, messaging and stock sync make good examples because each one pairs a trigger with a specific movement of data.
- A checkout page sends a charge request to Stripe’s API, authenticated with a secret key over HTTPS. Stripe reports the outcome back as webhook events.
- On the CRM side, a form submission creates a lead record in Salesforce through its REST API, which supports creating, reading, updating and deleting records.
- When a customer texts a Twilio number, Twilio sends an HTTP POST or GET request to the webhook URL the business configured. The application replies with TwiML, which tells Twilio what to do next.
- Stock sync is the plain one. A store pulls supplier inventory counts on a schedule and updates product availability.
The direction of the call differs between them. Stripe and Twilio call your application when something happens, while a CRM or a supplier feed usually waits to be called.
Each of these is a third-party integration, so the provider’s documentation sets the rules: which fields exist, how often calls are allowed, which version applies. Salesforce ships a new REST API version with every release, and Winter ’27 carries API version 68.0, one step on from 67.0 in Summer ’26 (Salesforce developer documentation).
Which Protocols and Data Formats Do API Integrations Use?

REST with JSON is the default you’ll meet most often. Older enterprise systems still run SOAP with XML. GraphQL suits clients that pick their own fields, and gRPC is built for fast calls between internal services.
The connecting system usually decides for you. When a team does get to choose, a closer look at REST versus GraphQL for web apps covers the trade-offs.
REST, SOAP, GraphQL and gRPC Compared

| Style | Data format | Best fit | Main limitation |
|---|---|---|---|
| REST | JSON, sometimes XML | Public and SaaS APIs | Over-fetching, many round trips |
| SOAP | XML | Formal contracts in older enterprise systems | Verbose payloads, heavier tooling |
| GraphQL | JSON | Clients choosing exact fields | Harder caching and query cost control |
| gRPC | Protocol Buffers over HTTP/2 | Internal service-to-service calls | Binary format, awkward in browsers |
gRPC works differently from the other three. Per the gRPC project documentation, a service is described in a .proto file using Protocol Buffers, client and server code is generated from it, and calls travel over HTTP/2 with support for bidirectional streaming.
JSON vs XML

Pick JSON unless the other system forces XML. JSON payloads are lighter and native to JavaScript. XML is more verbose, though it brings schema validation through XSD, and SOAP requires it.
Webhooks vs Polling for Data Updates

Push delivery can fail, and providers plan for that. In live mode, Stripe retries a failed webhook delivery for up to 3 days with exponential backoff, according to its documentation.
Push updates through webhooks reach your endpoint the moment an event fires, but downtime on your side can still lose them.
Webhooks are near-instant and waste no calls, yet delivery can fail. Polling is simple and predictable, though it’s delayed by the polling interval and spends calls on empty checks.
Most production integrations combine both. Webhooks keep data current, and a periodic query for missed events closes the gaps, a reconciliation route Stripe’s documentation describes.
How Integrators Read an API Contract
The OpenAPI Specification describes a REST API in a JSON or YAML file: endpoints, parameters, responses and security schemes. Tools such as Swagger and Postman import that file to generate documentation and test calls.
Version matters here. OpenAPI 3.1.0 (February 15, 2021) moved schema support to JSON Schema 2020-12 and shipped breaking changes, which is why the OpenAPI Initiative publishes a separate upgrade guide from 3.0 to 3.1.
Since 3.1, a description can also document webhooks the API sends. The changelog lists 3.2.0 as published on September 19, 2025.
How API Integrations Authenticate and Stay Secure
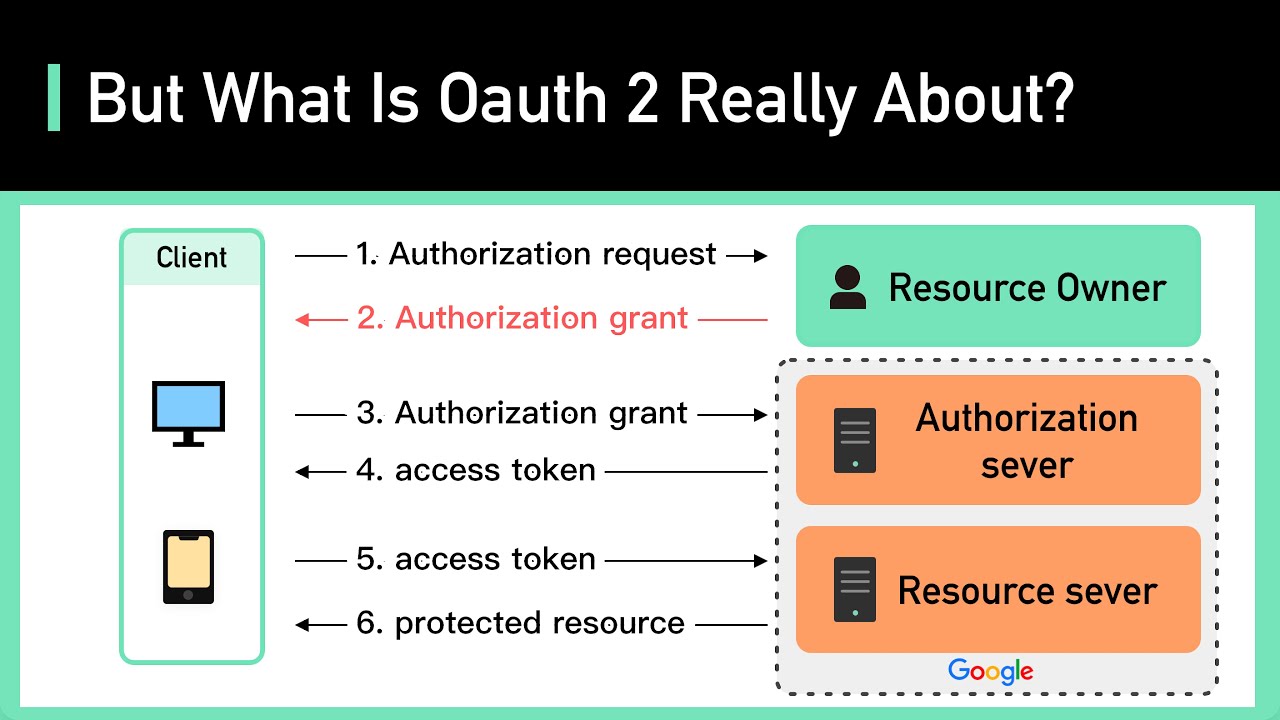
Most integrations prove permission with an API key or an OAuth 2.0 access token, and JSON Web Tokens turn up between internal services. Whichever it is, the credential travels over HTTPS on every call.
Which one fits depends on who is acting. A server working on its own account usually gets a key. If a user is delegating access, that’s OAuth. Between services, JWT.
OAuth 2.0 and JWT are both forms of authentication built on tokens, where the caller presents a short-lived credential in place of a password.
API Keys
Stripe secret keys start with sk_test_ in test mode and sk_live_ in live mode. Calls use HTTP Basic Auth with the key as the username, over HTTPS only (plain HTTP calls fail). Restricted keys, IP limits and rotation when staff leave keep the exposure down.
The usual failure is a key committed to GitHub or shipped in client-side code. Stripe’s documentation warns against sharing secret keys in either place.
OAuth 2.0
RFC 6749 (IETF, October 2012) defines OAuth 2.0 as a framework that lets a third-party application obtain limited access to an HTTP service, either on behalf of a resource owner or on its own behalf. It replaced OAuth 1.0.
Access is limited by scopes and expires, with refresh tokens used to renew it. That makes OAuth the right call when an integration acts for end users, such as a connector reading each sales rep’s calendar.
JSON Web Tokens
A JWT is a compact signed token carrying claims such as who the caller is and when the token expires.
The receiving service verifies the signature and expiry before trusting it, which suits service-to-service calls where no user is present. A token with a long expiry and no revocation path is the usual weak point.
For a server acting on one account, a restricted API key is enough. Once users grant access, switch to OAuth 2.0. JWT fits between services you control. And never put a secret key in a mobile app.
What Are the Types of API Integration?
Point-to-point links, hub-and-spoke middleware, iPaaS platforms and event-driven streaming are the main patterns, and the real-time versus batch split cuts across all of them. How many systems you have and how fast the data needs to move decide which one fits.
Point-to-Point Integration
Two systems, one direct connection. It’s the fastest pattern to build and the right one when exactly two applications exchange data.
The cost shows up as systems are added. Five applications wired pairwise need up to 10 separate connections, each with its own credentials, field mapping and failure handling.
Hub-and-Spoke and Middleware
A central hub sits between the applications, so each one connects only once. Transformation, routing and logging all live in one place, which is the appeal.
The downside is that the hub becomes a single point of failure, and someone has to own it.
iPaaS and No-Code Platforms
Gartner’s Peer Insights definition describes iPaaS as a vendor-managed cloud service for building integrations between applications, services and data sources, inside and outside an organization. Most are used through low-code or no-code environments.
Zapier is the best-known example. A trigger in one app starts actions in another, with no code. Only successful actions count toward its task limit, and on plans without pay-per-task billing, new runs are held once the limit is reached (Zapier Help Center).
Workato and MuleSoft both sell iPaaS platforms. A typical one ships prebuilt connectors plus logic such as conditions, loops and error handling for assembling integration flows, according to Workato’s iPaaS documentation.
Event-Driven Integration
Apache Kafka is an event streaming platform where producers publish events and consumers subscribe to them, per the Apache Kafka documentation. Kafka Connect adds continuous import and export between Kafka and systems such as relational databases.
The producer never calls the consumer directly, which is the core of an event-driven architecture. A new consumer can subscribe without any change to the producer.
Real-Time vs Batch Exchange
Real-time data moves when an event fires. It’s the right fit for payments, stock levels and alerts, and it gets expensive when the target system rate-limits. Batch moves data in scheduled groups, which works for nightly reports and large syncs and falls apart when a customer is waiting on the result.
Most teams run both, real-time for the customer-facing path and batch for reconciliation.
Build or Buy: What Does an API Integration Cost?
One in-house integration costs tens of thousands of dollars to build and a recurring slice of engineering time to keep running. Upkeep after launch, not the first build, decides whether building or buying is cheaper.
Key Figures From Published Estimates
- About 6 months is how long a product team needs to build one performant connector (CData)
- Initial build cost comes to $54,400 per integration (Truto)
- Running one connector in-house costs $50,000 to $200,000+ per year (Truto, 2026)
- Initial development makes up 30 to 40% of total cost of ownership (SPK Associates)
All four come from vendors or consultancies that sell integration services, and they are estimates rather than survey data. They also measure different things (elapsed time, one-off cost, annual cost, share of lifetime cost), so they cannot be added together. Even one vendor’s pages disagree: Truto also publishes build costs of $10,000 to $50,000+ per integration elsewhere. Treat them as orders of magnitude.
Custom Build
Building gives you full control over mapping, retries and data handling, and there’s no per-task or per-connector licence to pay. It’s also the right call when the integration is part of what you sell.
The costs are less visible. Every provider’s API differs, so code does not carry over from one connector to the next (CData). Engineers end up working on plumbing instead of the product, and maintenance continues for the life of the connector.
Prebuilt Connector or iPaaS
Faster to launch, and the cost moves from engineering hours to a subscription.
You can be live in days or weeks instead of months, with authentication and field mapping packaged in advance, and the vendor typically absorbs changes to the provider’s API. Pricing grows with volume, as with Zapier’s task-based plans. Custom logic also hits the platform’s limits, and moving off it later means rebuilding.
Decision Rule
Build when the integration is a differentiator, or when it connects two small, stable internal systems. SPK Associates names the second case as the one where a do-it-yourself build holds up.
Buy for standard connectors to common SaaS tools. Whichever route wins, budget for maintenance after launch from day one, including credential rotation, version upgrades and monitoring.
When Does an API Integration Break Down?
Rate limits, version changes, timeouts that leave a write half-done, data mapping errors and plain wrong-tool cases account for most breakage. All but the last can be designed around.
Rate Limits
GitHub allows 60 unauthenticated REST requests per hour per IP address and 5,000 per hour for an authenticated personal access token (GitHub documentation). A sync built on the first number stalls on the first busy morning.
Past the cap, GitHub answers with 403 or 429, and RFC 6585, which defines 429, allows a Retry-After header stating how long to wait. The server-side half of this behavior is API rate limiting, and the client has to cooperate with it.
- Read Retry-After first, and when a primary limit is hit, wait until the time in the x-ratelimit-reset header
- Back off exponentially when the header is missing
- Spread requests out, because GitHub also applies secondary limits that react to bursts and concurrency, and it states they can change without notice
GitHub warns that an integration which keeps sending requests while it is rate limited can be banned.
Version Changes
GitHub keeps the previous REST API version supported for at least 24 months after a new one ships. Versions are named by release date, and an unsupported one returns 410 Gone as of the current documentation.
Salesforce runs on a different clock. Each API version is supported for a minimum of three years from first release, with at least one year of notice before support ends. Versions 21.0 through 30.0 have been retired since Summer ’25, and calls to them return 410:GONE. Versions 31.0 through 40.0 are still supported but now have a published retirement notice.
The two windows differ by a year, so an upgrade schedule that works for one provider fails for the other. GitHub’s earlier documentation listed a 400 error for an unsupported version, so check the current docs instead of hard-coding the status code.
An integration pinned to an old version works until the day it stops. Tracking each provider’s API versioning notices belongs on a named person’s calendar.
Timeouts and Partial Failures
A write request that times out has an unknown outcome. Either the record exists on the other side or it doesn’t, and the client cannot tell which.
GET and DELETE are idempotent by definition, so retrying them is safe. For POST, send an idempotency key where the provider supports one, or query for the record before retrying.
Retry logic without idempotency is how duplicate invoices happen.
Data Mapping Errors
Text where a number is expected is the classic one. Null versus missing fields cause quieter trouble, and so do timestamps without a time zone.
Validate the payload before sending it, and log every rejected record with the reason.
When API Integration Is the Wrong Tool
Sometimes there’s no API at all, only file exports or a web interface. A scheduled file import is simpler than imitating a user session.
A one-time bulk transfer is another case. Moving a large dataset through rate-limited endpoints is slower than the provider’s bulk import tool, where one exists.
Reference data that rarely changes doesn’t need a live link either. A weekly export beats an integration that needs monitoring.
How Do You Build and Test an API Integration?

None of this is exotic, but skipping the early steps is how teams end up debugging against live data.
- Read the provider’s documentation and note the authentication method, rate limits, API version and pagination style.
- Get sandbox or test-mode credentials. Never develop against live data.
- Send each request by hand from Postman or curl and inspect the real responses before writing any code.
- Map source fields to target fields and write the transformation, including type conversions.
- Add error handling: exponential backoff on 429 and 5xx responses, no retry on 4xx errors caused by bad input, an idempotency key on writes, and logs that carry request IDs.
- Test the failure paths, not only the happy path.
- Deploy with production credentials, a pinned API version, and alerts on error rate and missed events.
Testing Failure Paths Before Users Do
An integration test sends real requests to the provider’s sandbox and checks the response and the resulting state in both systems.
Microsoft’s Dev Proxy sits between an app and the API and returns GitHub-style rate-limit responses, including the 429, so retry code runs before launch (Microsoft Learn).
- Expired or revoked token
- Empty payload and oversized payload
- Rate-limit response with and without Retry-After
- Timeout on a write request
Sandbox limits and latency differ from production, so a passing test run does not prove production behavior.
Going Live
Switching to the production environment changes credentials, limits and data volume all at once. Keep secrets in a secrets store, never in the repository.
Pin the API version in the request instead of relying on the account default. Then monitor error rate, latency and missed events from the first day.
API Integration FAQ
Is API integration the same as middleware?
No. Middleware is software that sits between applications and handles transformation, routing and delivery, so it’s one way to build an integration.
A direct API call between two systems is also an integration, with no middleware involved.
How does API integration differ from EDI?
EDI exchanges standardized business documents, such as purchase orders and invoices, between trading partners, often in scheduled batches.
API integration calls another system on demand over HTTP, so it suits real-time lookups and actions. EDI suits formal document exchange between companies.
What does an API gateway do, and how does it relate to API integration?
Requests to an API pass through the gateway first. It routes them to backend services and applies authentication and rate limits along the way.
IBM treats API management and integration as distinct but complementary. An API gateway governs the traffic of one API, while an integration connects two systems.
Can a non-developer set up an API integration?
Yes, for common app pairs. No-code platforms such as Zapier let a user pick a trigger in one app and an action in another, with no code written.
Custom logic, unusual fields and high volume still need a developer. Someone who understands the data should also approve the field mapping.
Which signals should a team monitor once an integration is live?
Watch error rate by status code, latency, rate-limit responses and failed or missed deliveries, and set an alert on each.
Log a request ID with every call, so a failed sync can be traced across both systems. A scheduled comparison of record counts on each side catches silent gaps.
Who Owns an API Integration After Launch?
A named engineer or team owns each API integration after launch, including its credentials, monitoring and version upgrades. Without that owner, alerts go unread and a retired version surfaces as a production outage.
The order of the next moves matters. Assign an owner and an alert route first. Then calendar each provider’s version retirement date, and after that replace direct links with a hub or iPaaS.
On connection count alone, a hub wins from the fourth system, with 6 pairwise links against 4 hub connections.
A team calling both GitHub and Salesforce APIs should review versions at least every 24 months, the shorter of their two published support windows.
For the interface most integrations call, start with how a RESTful API defines its resources and methods.

- How Businesses Can Build a Smarter and More Secure File Storage Strategy - November 4, 2026
- C cheat sheet - November 3, 2026
- Best Practices for Designing Intuitive Navigation in Web Applications - November 3, 2026


