

Teammates push while you’re away from the keyboard, and git fetch is how you find out what they pushed. It downloads new commits, branches and tags into remote-tracking branches such as origin/main, and your working directory and local branches stay exactly as they were.
Most people run it to read incoming work before choosing between a merge and a rebase. git pull skips that choice and does the integration for you, which is the main difference between the two.
There’s one documented exception. If a refspec names a local branch as the destination, git fetch updates that branch directly, and it refuses to do so for the branch you currently have checked out (Git documentation, git-fetch manual for Git 2.56.0, September 2026).
What Does git fetch Do?

Git connects to the remote (origin, unless you say otherwise) and compares the remote’s refs with the ones it already knows. It downloads only the objects you’re missing. Then remote-tracking branches like origin/main move to the new tips.
The Git manual describes the command as pulling refs, plus the objects needed to complete their histories, from another repository. The source can be a hosted remote repository on GitHub or GitLab, a plain URL, or a folder on the same machine.
Your local branches don’t move. The fetched commits sit on origin/main until you merge, rebase or check them out.
Pro Git puts it bluntly: fetch downloads data and never merges it into your work on its own.
What git fetch Updates and What It Leaves Alone
A fetch writes to the object database, to the remote-tracking branches under refs/remotes/, to tags that point into the fetched history, and to .git/FETCH\_HEAD. That’s the full list. The working directory, your uncommitted changes and every local branch are left alone.
FETCH\_HEAD holds the ref names and object names from the most recent fetch. Scripts read it, and so does git pull.
It also makes one-off peeks possible. The manual’s own example fetches the maint branch straight from a kernel.org URL that isn’t a configured remote, then runs git log FETCH\_HEAD to read the history. Git’s built-in housekeeping cleans up the fetched objects later.
A few details worth knowing (Git documentation, git-fetch manual for Git 2.56.0, September 2026):
- Each new fetch overwrites FETCH\_HEAD unless you pass –append
- –no-write-fetch-head skips writing the file, and –dry-run never writes it
- Tags that point into the fetched history come along by default
- With the default setup, origin’s branches land under refs/remotes/origin/
How to Run git fetch

Plain git fetch updates from the default remote. That’s origin unless the current branch has an upstream configured, and then the upstream’s remote wins (Git documentation).
| Command | What it fetches | Typical use |
|---|---|---|
| git fetch | Default remote, all its branches | Routine check for new work |
| git fetch origin main | Only main from origin | Looking at one branch |
| git fetch –all | Every configured remote | Fork plus shared repository setups |
| git fetch –dry-run | Nothing, only reports | Preview before downloading |
A clone sets the upstream of the default branch automatically, so a bare git fetch follows it from the start.
–all skips any remote that has remote.<name>.skipFetchAll set. If you set fetch.all to true, plain git fetch covers every remote, and –no-all switches that off for a single run.
Say you add a collaborator with git remote add pb <url> and run git fetch pb. You’ll see lines like * [new branch] master -> pb/master. Their master is now available locally as pb/master, ready to inspect or merge (Pro Git book).
How Refspecs Decide What git fetch Downloads
A refspec is written as +<src>:<dst>. The source is the remote ref and the destination is the local ref to update. The plus sign is optional, and it allows non-fast-forward updates.
Every clone stores this default in .git/config:
fetch = +refs/heads/*:refs/remotes/origin/*
The left side matches every branch on origin. The right side stores each one as a remote-tracking branch under refs/remotes/origin/.
Configured refspec versus command-line refspec
That one config line does different jobs depending on how you call fetch.
With no refspec on the command line, git fetch origin uses the configured value for both what to fetch and where to store it. Give it a refspec, as in git fetch origin main, and only main is downloaded. The configured value then just decides which remote-tracking branch, if any, receives it.
The –refmap option replaces that mapping for a single run. To change the stored mapping for good, edit the fetch line in .git/config or use the git config command.
Forced updates and local branch targets
A destination under refs/heads/ updates a local branch. It’s the one case where fetch touches your own work.
The manual’s example, git fetch origin +seen:seen maint:tmp, creates or updates the local branches seen and tmp from the remote’s seen and maint. Because of the plus sign, seen gets updated even without a fast-forward. tmp doesn’t.
So the tutorials saying fetch never affects local branches are simplifying. Put a refs/heads destination in the refspec and it does.
Tags have stricter rules. Since Git 2.20 (December 2018), an update to refs/tags/\* is rejected without a leading + or –force, while older versions accepted every tag update (Git documentation, as of Git 2.56.0).
How to Review Fetched Changes and Bring Them In
Once the fetch is done, compare your branch with its remote-tracking branch. If the incoming commits look fine, merge or rebase. Reviewing takes a couple of commands, and bringing the work in takes one.
git fetch origindownloads the new commitsgit log ..origin/mainlists what the remote has that your branch lacksgit diff origin/mainshows the file-level differencesgit merge origin/mainorgit rebase origin/mainbrings the commits in
The range in step 2 is shorthand for HEAD..origin/main, meaning commits reachable from origin/main but not from your current HEAD (gitrevisions manual). Whatever git log prints there is exactly what a merge would bring in.
The range syntax is worth memorizing, because it answers most “where do I stand” questions:
..origin/mainshows the commits you would receiveorigin/main..shows local commits the remote doesn’t have yetHEAD...origin/mainshows commits unique to either side, which makes it the quickest divergence check
When that last range prints commits on both sides, the branches have diverged. A plain git merge then creates a merge commit, and a rebase replays your commits on top of the fetched ones.
If only the first range prints anything, a fast-forward is possible and no merge commit appears.
Checking out a branch that only exists on the remote
git switch creates a local tracking branch automatically when exactly one remote has a branch with that name (git-switch manual).
git switch new-topic behaves like git switch -c new-topic --track origin/new-topic. The guess only works against remote-tracking branches that already exist locally, so the fetch has to come first.
git checkout new-topic does the same and sets the upstream.
With several remotes, set checkout.defaultRemote=origin. An ambiguous branch name then resolves to origin instead of failing.
git fetch vs git pull
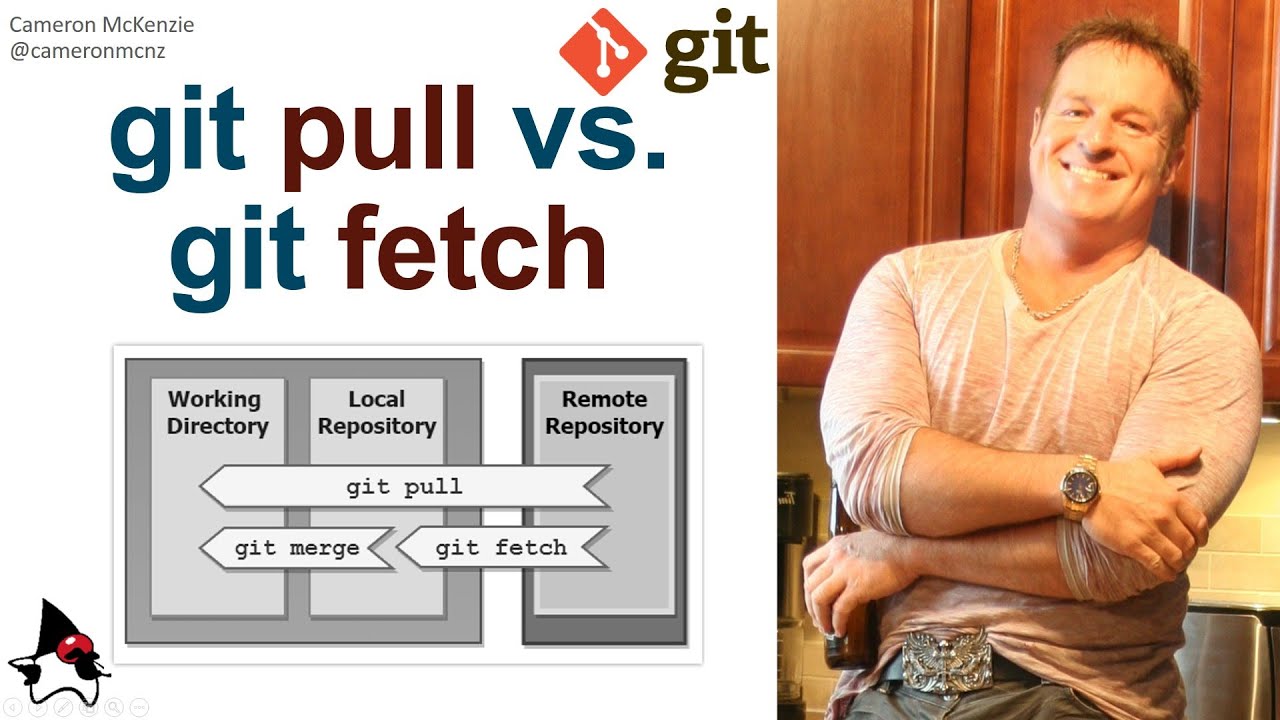
git pull is git fetch with an integration step bolted on, either a merge or a rebase. git fetch stops after the download.
With no arguments, git pull runs git fetch first and then integrates the branch’s upstream into the current branch (git-pull manual).
| Feature | git fetch | git pull |
|---|---|---|
| Downloads new commits | Yes | Yes |
| Updates remote-tracking branches | Yes | Yes |
| Moves the current local branch | No | Yes |
| Touches the working directory | No | Yes, when the merge or rebase applies |
| Conflict risk | None | During the merge or rebase |
What pull does after the download
How pull integrates depends on the mode you pick. –ff-only updates by fast-forward and fails if the local branch has diverged. –rebase runs git rebase, –no-rebase runs git merge, and –squash runs git merge –squash.
The manual warns that pulling with git rebase is a potentially dangerous mode, because it rewrites history that may already be published. If a merge or rebase hits conflicts you don’t want to deal with, git merge –abort or git rebase –abort gets you out.
A pull with an explicit branch is a fetch and a merge in one line. git pull origin next equals git fetch origin followed by git merge origin/next.
The sources don’t fully agree here. The Pro Git book says git pull warns since Git 2.27 (June 2020) when pull.rebase is unset, and it describes the default as a fast-forward when possible, otherwise a merge commit.
The git-pull manual for Git 2.56.0 (September 2026) names --ff-only as the default when no reconciliation method is set, which fails on diverged history instead of merging. The book’s note is written around 2.27 behavior, so check git --version and set pull.rebase or pull.ff explicitly.
Fetch first or pull straight away
Fetch first whenever the branch carries work the remote hasn’t seen. The same goes for uncommitted changes, or any time you’d like to read the incoming commits before they land.
Pulling directly is fine with a clean working tree and no local commits on the branch, since a fast-forward is all it can do then.
–autostash lets pull run on a dirty tree, though reapplying the stash afterward can produce conflicts of its own (git-pull manual).
Fetch plus git log is two commands. An unexpected merge commit is harder to undo.
Options and Settings That Change How git fetch Behaves

Most adjustments come down to –prune, –prune-tags, –tags, –depth and –jobs. All of them except –depth have a persistent setting, so you can configure them once and stop typing flags.
| Option | Effect | Persistent setting |
|---|---|---|
| –prune | Removes remote-tracking references that no longer exist on the remote | fetch.prune, remote.<n>.prune |
| –prune-tags | With –prune, removes local tags missing from the remote | fetch.pruneTags |
| –tags | Fetches every remote tag on top of the normal fetch | remote.<n>.tagOpt |
| –depth=<n> | Limits history to n commits from each branch tip | None |
| –jobs=<n> | Runs up to n fetch operations in parallel | fetch.parallel |
Git keeps references to deleted remote branches unless told otherwise. On big, busy repositories those leftovers can slow commands down and clutter the output of things like git branch -a (Git documentation).
Pruning also exists as its own command. The git remote prune command removes stale references without downloading anything.
Tag handling has its own controls. –no-tags stops the automatic following, –tags adds every tag on the remote, and remote.<n>.tagOpt stores the default per remote. If you want the tags basics first, start there.
Parallel fetches across several remotes are usually faster, but the default is sequential.
I’d set fetch.prune globally and leave fetch.pruneTags off, unless one remote owns every tag you keep locally.
When git fetch Does Not Do What You Expect
Fetch leaves your working directory alone, but not every flag is harmless and not every result is obvious. A handful of documented cases cause most of the surprises.
- Your local branch stays behind. Fetch moves origin/main and nothing else, so git status keeps reporting how many commits each side added since they forked. Merge, rebase or pull with –ff-only to close the gap.
- A checked-out branch refuses a direct update. By default fetch won’t update the head that matches the current branch, so
git fetch origin main:mainfails while main is checked out. The –update-head-ok override exists for git pull’s internal use, and the manual tells everyone else to leave it alone. - Rewritten remote branches get rejected. After a rebase on the remote, the new tip isn’t a descendant of the old one. An explicit refspec without the leading + rejects that update and marks it with a ! in the fetch output, while the default refspec forces it.
- –prune-tags deletes local tags that are missing on the remote, including ones you created yourself, and it behaves as if the refs/tags/\:refs/tags/\ refspec were added. With several remotes feeding one tag namespace, it can wipe tags that never came from the pruned remote.
- Shallow clones refuse some updates. Fetching into a shallow repository rejects refs that require updating .git/shallow unless you pass –update-shallow. –unshallow converts the repository to a complete one, and tags for commits added with –depth aren’t fetched.
A shallow repository is what git clone produces when you pass –depth.
None of these cases touch uncommitted files. They change references and history, which is why they’re easy to miss.
git fetch FAQ
Is git fetch the same as git clone?

No. git clone creates a new local repository from a remote, names the remote origin and sets the upstream of the default branch. git fetch works inside an existing repository and only downloads objects and moves remote-tracking branches.
How do you fetch a pull request branch from GitHub?
Run git fetch origin pull/ID/head:BRANCH\_NAME, with the pull request number in place of ID, then git switch BRANCH\_NAME (GitHub Docs).
The refs/pull/ namespace is read-only, so pushing commits back there is rejected. Push a new branch instead.
Why does git fetch fail with Permission denied (publickey)?
The server rejected your SSH connection, which points to credentials rather than to fetch itself. GitHub’s documentation walks through four checks: connecting to the wrong server, connecting as your username instead of the git user, no private key loaded in ssh-agent, or a public key missing from your account.
Test the connection with ssh -T git@github.com.
Is it safe to run git fetch with uncommitted changes?
Yes. Fetch never touches the working directory, so uncommitted edits stay exactly as they are.
Conflicts show up later, at the merge or rebase step. git pull –autostash can stash and reapply local changes around that step (git-pull manual).
Can git fetch turn a shallow clone into a full one?
Yes, as long as the source repository is complete. git fetch –unshallow converts the clone and removes the shallow limits.
–deepen=<n> adds n commits beyond the current shallow boundary, and –shallow-since=<date> extends history back to a chosen date.
How Often to Run git fetch

Run git fetch before every merge, rebase or pull, and leave background downloads to a scheduled job. git maintenance start prefetches every registered remote hourly and doesn’t move a single remote-tracking branch.
The habit matters more than the automation. Fetching by hand prevents surprise merges, and scheduling only saves transfer time.
So fetch manually before integrating, set fetch.prune once globally, and register the repository for the hourly prefetch.
The prefetch task writes into refs/prefetch/ and skips tags, so origin/main stays put until you fetch yourself. The trade-off is that git status and git log show the old state until that real fetch, which then transfers little or nothing.
Hourly runs lock the object database, so a maintenance window longer than one hour skips a task when runs collide (git-maintenance manual, Git 2.56.0, September 2026).
When the merge after a fetch stops on conflicts, the guide to resolving merge conflicts in Git covers the next step.

- How to Turn On Dark Mode in Notepad++ (Built-In, No Plugin) - October 3, 2026
- PostgreSQL Cheat Sheet - October 2, 2026
- How to Repair a Corrupt SQL Server Database Without Any Data Loss - October 2, 2026


